Table of Contents
Choose Meta for feed-native visual concepts, Google Search for query-matched messaging, and Demand Gen/YouTube for visual hypotheses on Google. The right choice depends on the customer question you want to test. Google’s Demand Gen guidance recommends changing one variable and using a 50% traffic split. Its eligible Performance Max asset experiments are in Beta, with a recommended minimum of 4 to 6 weeks. Apply each recommendation to the experiment type it covers.
Meta Ads vs Google Ads creative testing: compare four environments
Use the same commercial hypothesis across platforms, but adapt the assets, what you compare and how you interpret the result.
| Question | Meta | Google Search | Demand Gen/YouTube | Performance Max |
|---|---|---|---|---|
| Customer context | Discovery in feeds and other placements | Expressed query intent | Visual discovery across Google inventory | Mixed intent across channels |
| Creative formats | Images, video, carousels | Responsive text assets | Images and video | Text, images and video |
| Experiment unit | Configured creative variants | Ad variation or campaign variant | Campaign variants | Eligible asset sets |
| Available controls | Creative and campaign settings | Messages, keywords and settings | Single changed variable | Experiment-defined asset treatment |
| Sales-focused primary metric | Purchase CPA or ROAS | Purchase CPA or ROAS | Purchase CPA or ROAS | Purchase CPA or ROAS |
| Reporting level | Experiment, campaign and ad | Experiment, ad and asset | Experiment, campaign and asset | Experiment, group and asset |
| Controlled result establishes | Configured variant difference | Message or campaign-treatment difference | Configured visual-treatment difference | Asset-set difference within system |
| What remains unresolved | Component effects in bundled concepts | Independent headline contribution | Transfer to other YouTube setups | Independent asset contribution |
| Interpretation pitfall | Optimized delivery mistaken for randomization | Selected combinations mistaken for headline winners | Eligibility mistaken for identical delivery | Cross-channel selection mistaken for asset causality |
Demand Gen is the closer Google comparison for Meta image and video hypotheses. Other YouTube campaign setups use different experiment mechanisms. Our creative workflows for agencies support asset preparation across client portfolios; a valid experiment still depends on test design.
Define a concept, execution or campaign-system test
Test customer angles before cosmetic variations when you are still unsure which customer belief drives purchase. Before production, define the business constraint, hypothesis, primary outcome and smallest useful improvement.
| Scope | What changes | What stays fixed | Supported conclusion |
|---|---|---|---|
| Concept | Coordinated hook, proof and presentation | Product, offer and delivery settings | Which complete customer proposition performs better |
| Execution | One element, such as opening text | Concept and remaining execution | Effect of that execution change |
| Campaign system | Bidding, targeting or channel eligibility | Other planned inputs | Effect of the configured system change |
A winning concept identifies the stronger bundle, not the contribution of each component. To isolate those contributions, follow Microsoft Research’s experimentation guidance and break complex changes into simpler hypotheses.
Meta: distinguish experiments from optimized ad delivery
Adding several ads to one ad set is not, by itself, a controlled creative experiment. Distinguish these testing and delivery options:
- Formal A/B experiment: use its allocation and comparison design, recording the tested variable and eligible population. Formulate a hypothesis and choose independent and dependent variables, following Meta Blueprint’s measurement course.
- In-campaign Creative Testing: check account availability and current setup rules. Results can be viewed through Experiments or the campaign while testing runs, according to Search Engine Journal’s walkthrough.
- Ordinary optimized delivery: Meta selects delivery among ads. Uneven impressions reflect the system’s selection under those conditions, not randomized exposure.
Audit placement eligibility, audience expansion and automated creative enhancements, which can change what people actually see.
A/B testing compares variants; lift measurement asks about incremental advertising impact, according to Meta Blueprint’s creative course.
Google: match the experiment to Search, Demand Gen or Performance Max
Search: test query-matched message families
Use supported ad variations for text changes, or custom experiments for broader campaign questions. Ad variations support responsive Search ads and changes across campaigns, according to Google’s experiment guidance.
Preserve keyword and query-intent coverage, destination alignment and campaign settings. For the same black dress, compare coherent message families:
| Family | Example headlines |
|---|---|
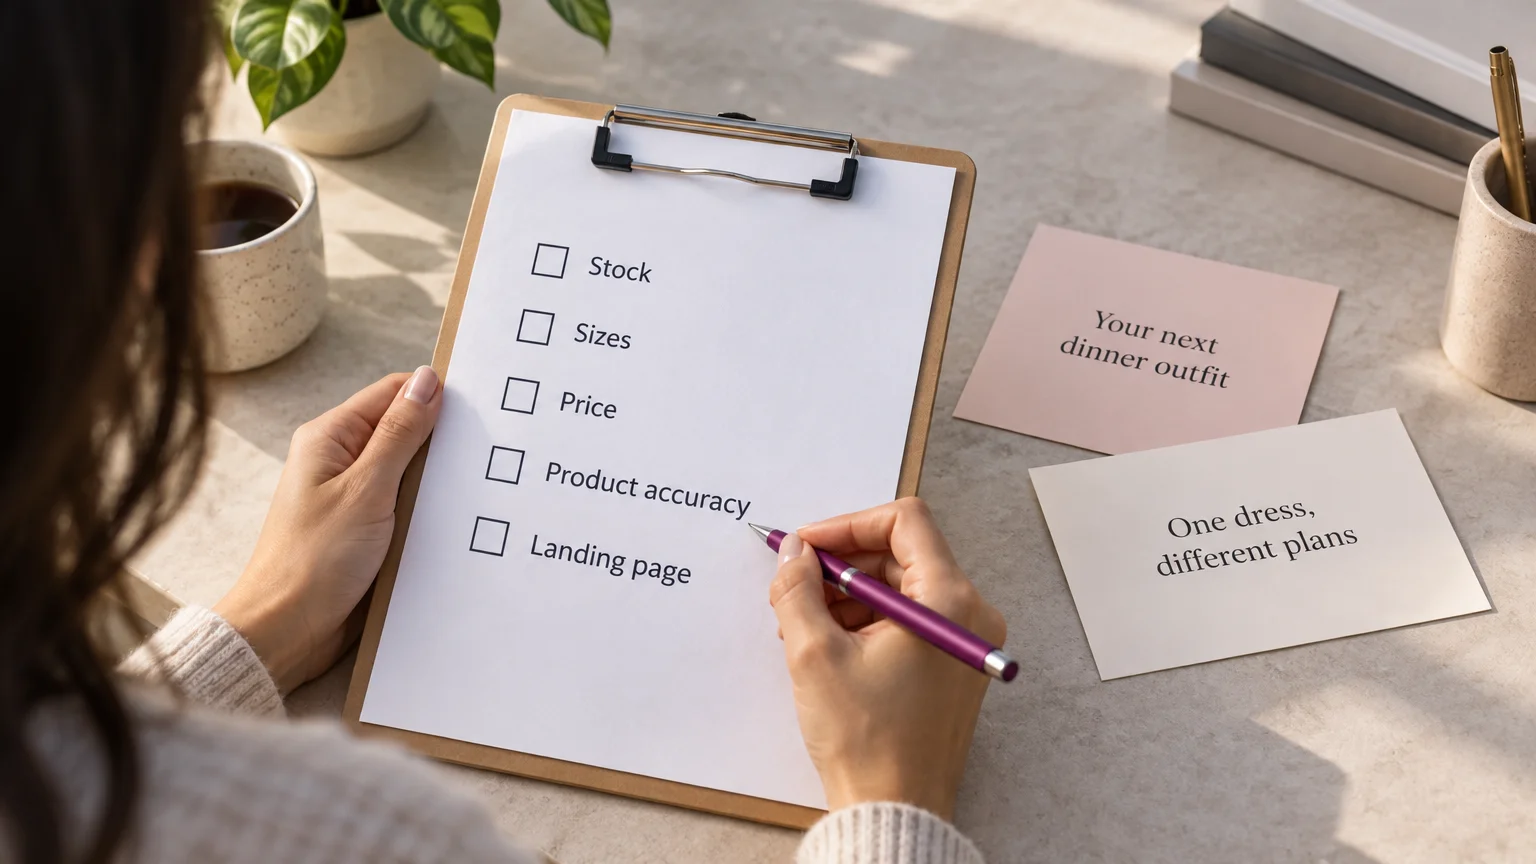
| Occasion-led | Black Dress for Dinner; Your Next Dinner Outfit |
| Styling versatility | One Dress, Different Plans; Style Your Black Dress |
Validate every claim against the product. Full asset statistics have replaced deprecated performance labels in Google’s Search asset reporting. Individual-asset ratios offer directional evidence, not isolated headline results, because assets appear in selected combinations.
Demand Gen: compare visual variants
Use Demand Gen for a controlled image or video comparison closer to Meta’s visual task. Keep other settings consistent and inspect actual audience and channel delivery.
Performance Max: compare eligible asset sets
Use eligible Performance Max asset A/B Beta experiments to compare asset sets within automated cross-channel delivery. The result applies to the asset set within that system; it does not isolate individual assets, which appear in combinations.
A black-dress test brief and fashion control audit
Test the opening message on one black-dress SKU while holding the product and offer fixed.
| Brief field | Decision |
|---|---|
| Business constraint | Purchase acquisition cost |
| Hypothesis | An occasion-led opening lowers purchase CPA versus styling versatility |
| Useful improvement | 20% lower purchase CPA |
| Variant A | Your next dinner outfit |
| Variant B | One dress, different plans |
| Guardrails | Garment accuracy, stock continuity and return-adjusted economics |
| Conversion delay | Use observed purchase-reporting lag before review |
| Next action | Scale, refine or rerun according to uncertainty and guardrails |
For video, preserve source footage, duration, audio and CTA. Change only opening text, keeping its timing, position and styling identical.
| Environment | Test adaptation | Conclusion limit |
|---|---|---|
| Meta | Eligible A/B comparison of opening-text variants | Opening-message effect in this setup |
| Demand Gen | Single-variable experiment using the same source video | Effect in this Google delivery environment |
| Search | Occasion versus versatility message families | Message-family effect within Search |
Fixed-settings audit: preserve SKU, price, offer, stock and size availability, destination page, audience eligibility, geography, placement/channel eligibility, bidding, conversion event, schedule and enhancement settings. Log unavoidable changes and flag compromised comparisons.
Delivery audit: record actual audience, device, placement and channel exposure. Audience and inventory mix can differ despite identical eligibility. Use experiment allocation for randomized comparisons.
Fashion audit: verify cut, color, texture and fit against the product. Log stockouts, missing popular sizes, promotions and page changes. Review returns as they mature: cheaper purchases can still produce worse economics.
Name exports by SKU, hypothesis, execution, platform, placement and version. Check current placement specifications, crop, text legibility, duration, audio and destination before launch. Archive accepted assets and tracking IDs.
Choose the primary metric, budget and stopping rule
Use purchase CPA when acquisition-cost efficiency is the objective; use value-based ROAS when order value matters and revenue tracking is trustworthy.
- Purchase CPA: spend divided by attributed purchases.
- ROAS: attributed purchase value divided by spend.
Neither captures margins, returns or incrementality alone. Attention, CTR, landing-page behavior and checkout progression help diagnose the path to purchase; keep the sales outcome primary.
Example: budget and timing for the black-dress test
Assume a $30 baseline CPA, 10 purchases daily across both arms, a 5-day reporting delay and an experiment planner estimate of 200 purchases in total.
- Commercial target: $30 × 20% = $6 improvement; $30 − $6 = $24 target CPA.
- Acquisition budget: 200 purchases × $30 = $6,000.
- Collection estimate: 200 purchases ÷ 10 daily purchases = 20 days.
- Reporting allowance: 20 days + 5 days = 25 days before the planned review of mature conversion data.
Baseline variability, allocation and the smallest meaningful change determine how much evidence you need. Sample-size planning requires baseline and effect-size assumptions, according to NIST’s sample-size guidance. Use the experiment’s planner and duration guidance.
Launch only after tracking and allocation checks. Set review dates, uncertainty criteria and stopping rules in advance. A winner needs mature conversions and a sufficiently precise comparison. Microsoft Research’s testing guidance warns that repeated checking requires methods that account for early peeking.
Across platforms, align purchase and revenue definitions, attribution windows, click/view credit, timestamps and conversion maturity. Parallel Meta and Google campaigns yield platform-specific ROAS under their attribution settings, not a randomized platform comparison. That requires its own allocation design.
Record the learning before scaling or adapting
Scale only when the result supports a commercially useful difference and the business guardrails hold. Use this record for every test:
| Record field | What to enter |
|---|---|
| Question and treatment | Hypothesis, mechanism, creative IDs and changed variable |
| Controls and delivery | Fixed settings, deviations and actual delivered mix |
| Measurement | Primary metric, attribution settings and conversion maturity |
| Evidence | Exposure, uncertainty range and useful-improvement threshold |
| Decision | Result classification, next action and review date |
- Commercially useful improvement: scale cautiously within the tested scope, checking stock and economics.
- Practically negligible difference: a sufficiently precise result supports moving to a stronger hypothesis.
- Material harm: stop the harmful variant and investigate the cause before retesting.
- Insufficient evidence: the uncertainty range spans outcomes that would lead to different decisions, such as a useful improvement and no useful improvement, or a useful gain and material harm. Extend according to plan, simplify or rerun.
Low delivery leaves an idea’s commercial value unresolved. Retain exposure and conversion-maturity details rather than declaring it a loser. Carry a Meta-winning idea into a new Google hypothesis and validate it in that environment.
Use our production tools without surrendering test controls
Use our Image Ads and Video Ads tools to prepare variants, then verify that only the intended differences remain. Our product-first video production supports 15 formats for 10 placements; choose the format and placements before production.
Review garment fidelity, copy, audio, crop and CTA, then archive approved exports. Our Ad Autopilot lets you review setup, publish a campaign paused and activate it when ready. Our campaign autonomy options include Observe for recommendations, Co-pilot for approval-led changes, and Autopilot for automatic campaign management. Use Observe or approval-based Co-pilot while test inputs must remain fixed.
Require approval for changes to preserved inputs. Review proposed budget, targeting and creative changes against the test plan. Configure randomized experiments in the relevant platform workflow; use campaign-management automation to support the approved setup.
Choose Meta, Google or both by the next decision
- Choose Meta for feed-native angles and visual execution. Ordinary optimized delivery is convenient but offers weaker causal isolation.
- Choose Google Search for query-matched messages, Demand Gen for visual hypotheses, or eligible Performance Max experiments for asset sets. Search cannot substitute for a video test.
- Use both for complementary questions when you can fund interpretable comparisons.
Write the hypothesis, identify what the experiment will compare and preserve the controls. Then review our campaign-management workflow to support the approved launch.